


About Me

I’m drawn to the space where behavioral science meets data: the signals hiding in behavior that tell you why someone chose this over that, the customer journeys inside a funnel, the moment you realize this is why people came back and that is why they didn’t.
I’m Ishika. I spent a little over two years at Dell Technologies on the customer experimentation team, where I built NLP tooling and Tia Insights Advisor (TIA), a self-serve chatbot that made experimentation insights searchable across the org, filed for patent in 2024. I’ve also spoken at Kaggle Days as an invited webinar speaker on experimentation fundamentals.
I recently finished my MS in Information Management at the University of Washington, working as a Graduate Research Scholar at the eScience Institute on large-scale astronomy tools with Caltech and Rice, and my capstone with Google.
Lately I’ve been using AI to accelerate all of this, and rebuilding older ideas with it, just to see what actually changes. My Experimentation Intelligence Agent (EIA) is the AI-native successor to TIA: same problem (surfacing experimentation insights on demand), new substrate.
Off-hours: psychology, music, singing, and reading 🎧 Reach out through the socials on the left.
I’m drawn to the space where behavioral science meets data: the signals hiding in behavior that tell you why someone chose this over that, the customer journeys inside a funnel, the moment you realize this is why people came back and that is why they didn’t.
I’m Ishika. I spent a little over two years at Dell Technologies on the customer experimentation team, where I built NLP tooling and Tia Insights Advisor (TIA), a self-serve chatbot that made experimentation insights searchable across the org, filed for patent in 2024. I’ve also spoken at Kaggle Days as an invited webinar speaker on experimentation fundamentals.
I recently finished my MS in Information Management at the University of Washington, working as a Graduate Research Scholar at the eScience Institute on large-scale astronomy tools with Caltech and Rice, and my capstone with Google.
Lately I’ve been using AI to accelerate all of this, and rebuilding older ideas with it, just to see what actually changes. My Experimentation Intelligence Agent (EIA) is the AI-native successor to TIA: same problem (surfacing experimentation insights on demand), new substrate.
Off-hours: psychology, music, singing, and reading 🎧 Reach out through the socials on the left.
I’m drawn to the space where behavioral science meets data: the signals hiding in behavior that tell you why someone chose this over that, the customer journeys inside a funnel, the moment you realize this is why people came back and that is why they didn’t.
I’m Ishika. I spent a little over two years at Dell Technologies on the customer experimentation team, where I built NLP tooling and Tia Insights Advisor (TIA), a self-serve chatbot that made experimentation insights searchable across the org, filed for patent in 2024. I’ve also spoken at Kaggle Days as an invited webinar speaker on experimentation fundamentals.
I recently finished my MS in Information Management at the University of Washington, working as a Graduate Research Scholar at the eScience Institute on large-scale astronomy tools with Caltech and Rice, and my capstone with Google.
Lately I’ve been using AI to accelerate all of this, and rebuilding older ideas with it, just to see what actually changes. My Experimentation Intelligence Agent (EIA) is the AI-native successor to TIA: same problem (surfacing experimentation insights on demand), new substrate.
Off-hours: psychology, music, singing, and reading 🎧 Reach out through the socials on the left.
I’m drawn to the space where behavioral science meets data: the signals hiding in behavior that tell you why someone chose this over that, the customer journeys inside a funnel, the moment you realize this is why people came back and that is why they didn’t.
I’m Ishika. I spent a little over two years at Dell Technologies on the customer experimentation team, where I built NLP tooling and Tia Insights Advisor (TIA), a self-serve chatbot that made experimentation insights searchable across the org, filed for patent in 2024. I’ve also spoken at Kaggle Days as an invited webinar speaker on experimentation fundamentals.
I recently finished my MS in Information Management at the University of Washington, working as a Graduate Research Scholar at the eScience Institute on large-scale astronomy tools with Caltech and Rice, and my capstone with Google.
Lately I’ve been using AI to accelerate all of this, and rebuilding older ideas with it, just to see what actually changes. My Experimentation Intelligence Agent (EIA) is the AI-native successor to TIA: same problem (surfacing experimentation insights on demand), new substrate.
Off-hours: psychology, music, singing, and reading 🎧 Reach out through the socials on the left.
Highlights
Skills & Tools





Portfolio
Experimentation Intelligence Agent
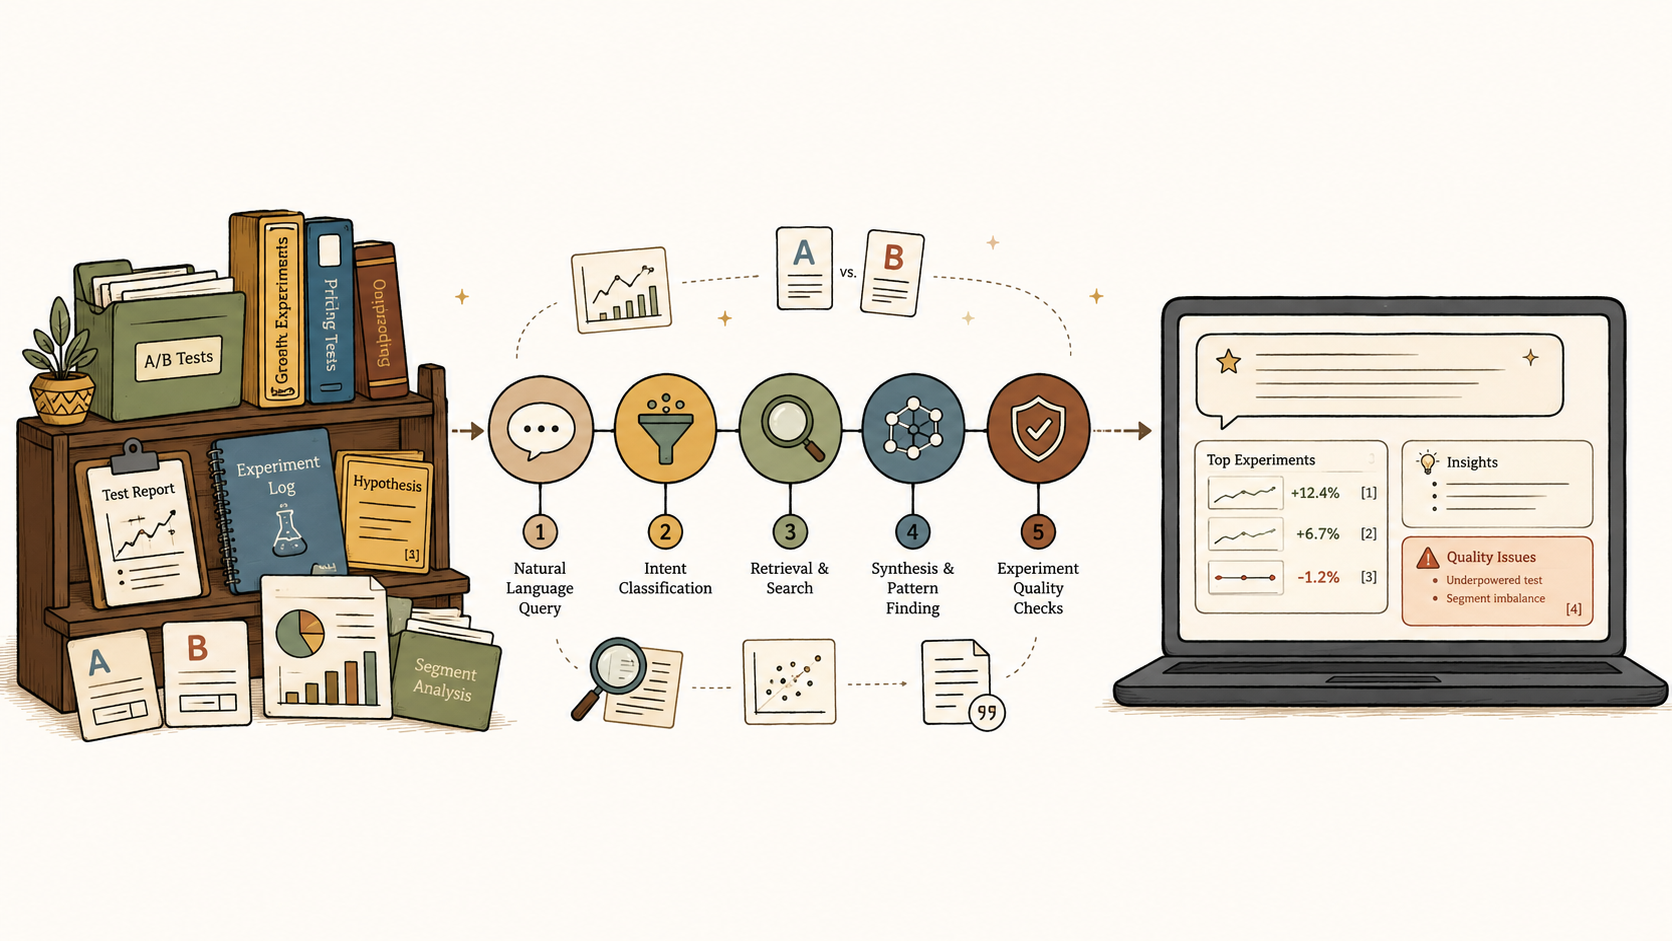
An agentic RAG system for natural language querying of historical A/B test results, with built-in bias detection for experiment validity. Multi-node LangGraph pipeline over a ChromaDB vector store of experiment metadata; local-first LLM inference with hosted-API fallback for production.
LangGraph · LlamaIndex · ChromaDB · sentence-transformers · FastAPI · Ollama · Claude API
Google Vanir · Python Extension (Capstone)
Extended Google's security patch detection tool Vanir to Python via Tree-Sitter CST integration, validated on 26/26 CVE/fix pairs from OSV. Expands Android OEM patch-compliance coverage. Workshop paper in progress.
Tree-Sitter · Python · CST parsing · Security · OSV


Travel Recommender and Itinerary Generator
A Travel Itinerary generator customised to the user's vacation type, budget and other details. The Itinerary suggests possible places the user would like to visit tailored to the available timings. This project considers only Jaipur, India as the destination city at the moment.
Streamlit · Folium · Plotly · Pandas

Cross Content Recommender
Cross-content recommender matching 18K+ books to movies using SBERT embeddings and contrastive learning (InfoNCE), with LLM-powered genre mapping across 461 book genres and FAISS indexing for real-time retrieval. Self-scraped datasets from Goodreads and IMDB.
SBERT · FAISS · Contrastive Learning · Claude API · Streamlit · FastAPI
Experience
Experience
Experience
Graduate Research Scholar: Sep'25–Jun'26 at eScience Institute, University of Washington
- Engineered an LLM-powered ADA accessibility remediation pipeline for UW research PDFs combining IBM Docling extraction, pikepdf structural rewriting, and a swappable multi-model backend (Claude, Hugging Face-hosted Gemma and Olmo) via unified API gateway, automating WCAG 2.1 AA fixes and cutting manual remediation effort ~70% with human-in-the-loop approval.
- Built an open-source Python library providing scalable lazy-loading access to Caltech's 96TB radio astronomy archive by implementing a unified API over S3 and local backends with Dask-backed chunked computation, enabling ~10x faster exploratory analysis for Caltech and Rice researchers vs. full-download workflows.
- Shipped two open-source Claude Code agent plugins for UW's research software engineering toolchain, automating cloud-native data workflow decisions: one benchmarks Zarr chunk-size tradeoffs across read/write/compute patterns; the other standardizes Zarr/Xarray compression and S3 upload.
Data Science Intern: Jun'25–Sep'25 at University of Washington, UW IT
- Built a multi-year revenue forecasting system for UW's financial planning team by engineering hierarchical temporal features over SQL Server data and training LSTM models in PyTorch, achieving ~12% MAPE on held-out periods and informing FY26 budget decisions.
Data Scientist 2: Feb'24–Aug'24 at Dell Technologies, Experimentation Team
- Lifted conversion rates 15% by designing a behavioral and transactional K-means customer segmentation pipeline in PySpark, then validating segment-targeted campaigns against generic baselines via controlled A/B tests with two-proportion z-tests.
- Built an implicit-feedback ALS collaborative filtering recommender on sparse behavioral signals (clicks, cart adds, purchases) and ran a controlled A/B test on 10–15% of live traffic, delivering 20% CTR lift (p < 0.10) over the production rule-based baseline.
- Cut manual reporting overhead 30% by automating ETL pipelines across multiple datasets via GitLab CI/CD, with monitoring and alerting that maintained 97% extraction reliability across daily runs.
Data Scientist 1: Aug'22–Jan'24 at Dell Technologies, Experimentation Team
- Engineered a production-deployed end-to-end self-serve NLP chatbot with custom NER, 96% intent classification accuracy, and dynamic response generation over Dell's 200+ annual A/B test repository, cutting experimentation-insight retrieval time 45% and replacing manual documentation search; patented Aug 2024 and adopted across the experimentation org.
- Trained one-vs-all LSTM classifiers in PyTorch on sequential hit-level clickstream data for per-category purchase propensity scoring across Dell's 5 laptop lines, achieving 88% per-class accuracy and generating A/B test hypotheses for targeted marketing campaigns.
- Simulated Bayesian inference and Thompson Sampling Multi-Armed Bandit strategies on historical A/B test data, demonstrating 30% test-duration reduction at equivalent statistical power, and authored a proposal driving org-wide adaptive experimentation adoption.
- Built an automated balanced-assignment clustering tool for marketplace A/B test groups, saving 300+ engineering hours annually and standardizing randomization across the experimentation team.
Data Analyst Intern: Jun'21–May'22 at Dell Technologies, Data Governance Team
- Resolved 50% null inconsistencies and drove 25% data completeness for downstream ETL via a Power BI data-quality dashboard; eliminated 15% data inconsistencies via data catalog mapping and lineage gap analysis in Manta, Collibra for GDPR-aligned governance.